ToolsEnabled Bench Beta · 0.3.1

Build the benchmark.
Keep the evidence.

ToolsEnabled Bench is a standalone research workbench for building inspectable benchmark studies. Compose tasks, declare the protocol, freeze the study, and carry its runtime and evidence into a runnable export. Bench 0.3.1 is also an MCP plugin your AI agent can drive.

MIT licensed/Runs locally/No ToolsEnabled account

01From snippets to a study

Compose, freeze,
check.

Version 0.3.1 keeps projects on your computer, requires no ToolsEnabled account, and includes a local MCP server so your AI agent can run the whole workflow. It is a separate product from ToolsEnabled Fleet. Included examples use authored, recorded controls.

  1. Compositional authoring

    Build prompts from reusable, typed snippets and nested compositions, with explicit variants and omissions.

    snippets · nesting · variants
  2. Controlled task generation

    Generate task sets from declared choices and seeds, with strata and recorded exclusions.

    choices · seeds · strata
  3. Freeze and qualification

    Bind the specification, runtime sources and analysis plan to a frozen study, then check its declared execution requirements.

    freeze · qualify
  4. Portable runnable exports

    Export the pinned runtime, required plugins and file hashes, with a CLI for verification, qualification, execution and analysis.

    verify → qualify → run → analyze
  5. Reproducible evidence reports

    Regenerate HTML and Markdown reports from retained attempts, responses and scoring evidence.

    HTML · Markdown

02The workbench

Real screens.
Recorded controls.

Captured from Bench 0.2.0 running locally in headless Chromium. The examples are authoring previews and recorded-control runs, not model measurements.

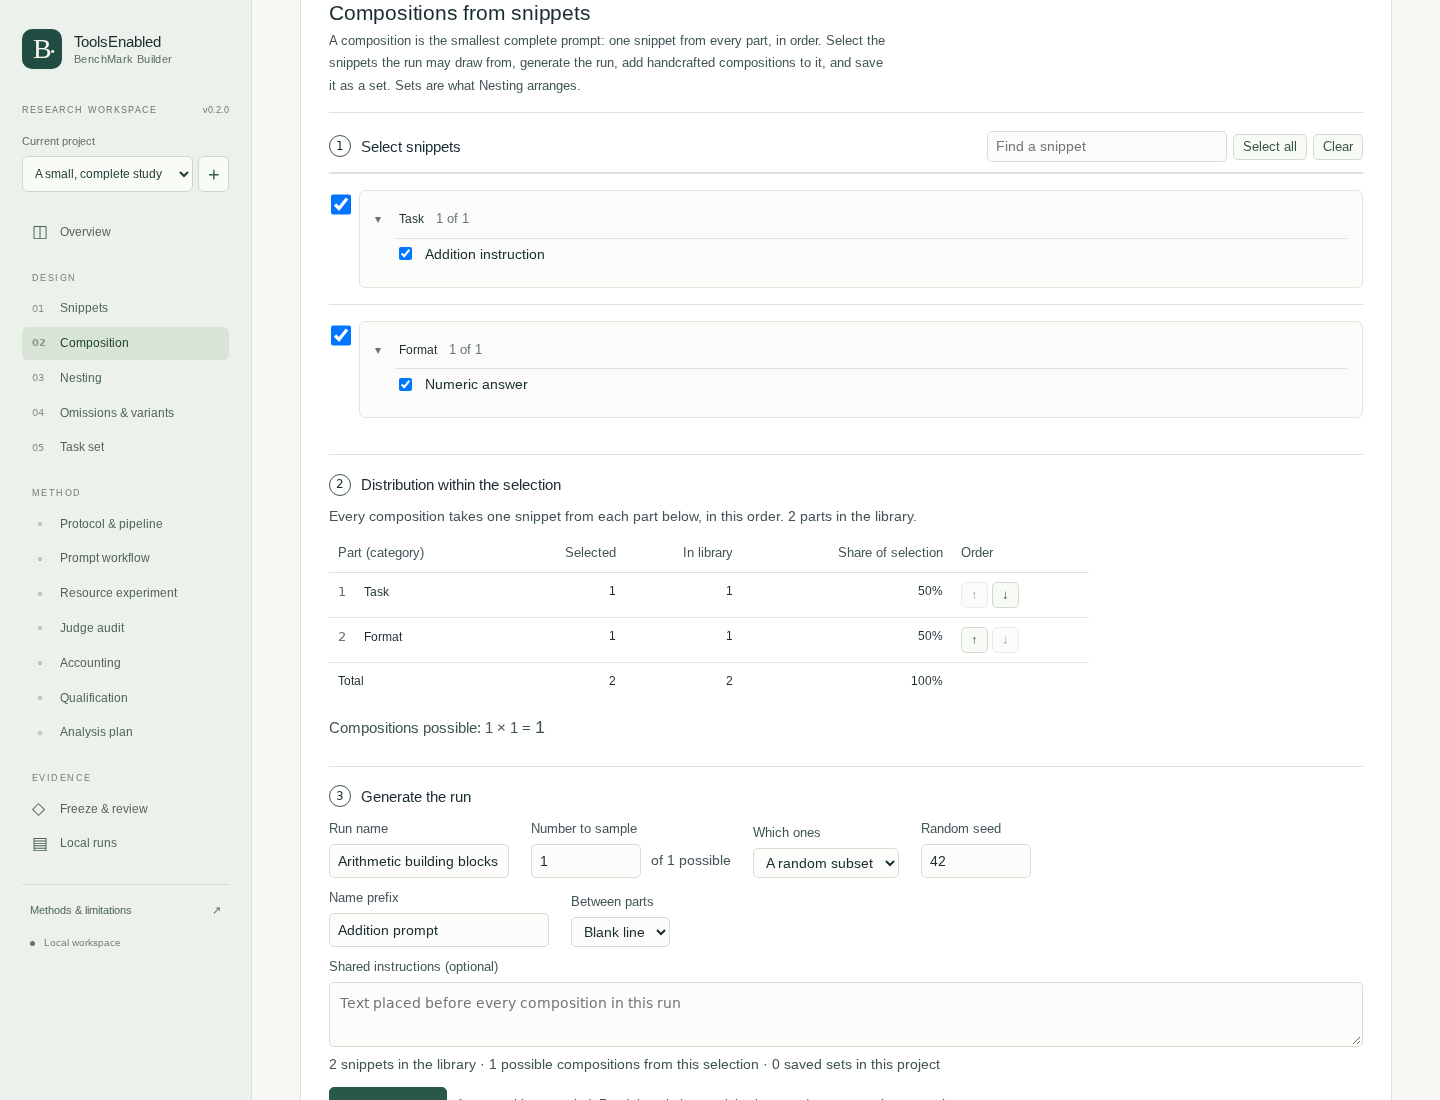
Reusable task and answer-format snippets are selected for a seeded composition. The library, part counts and generation settings remain visible.
Compositional authoring. Reusable task and answer-format snippets are selected for a seeded composition. The library, part counts and generation settings remain visible.
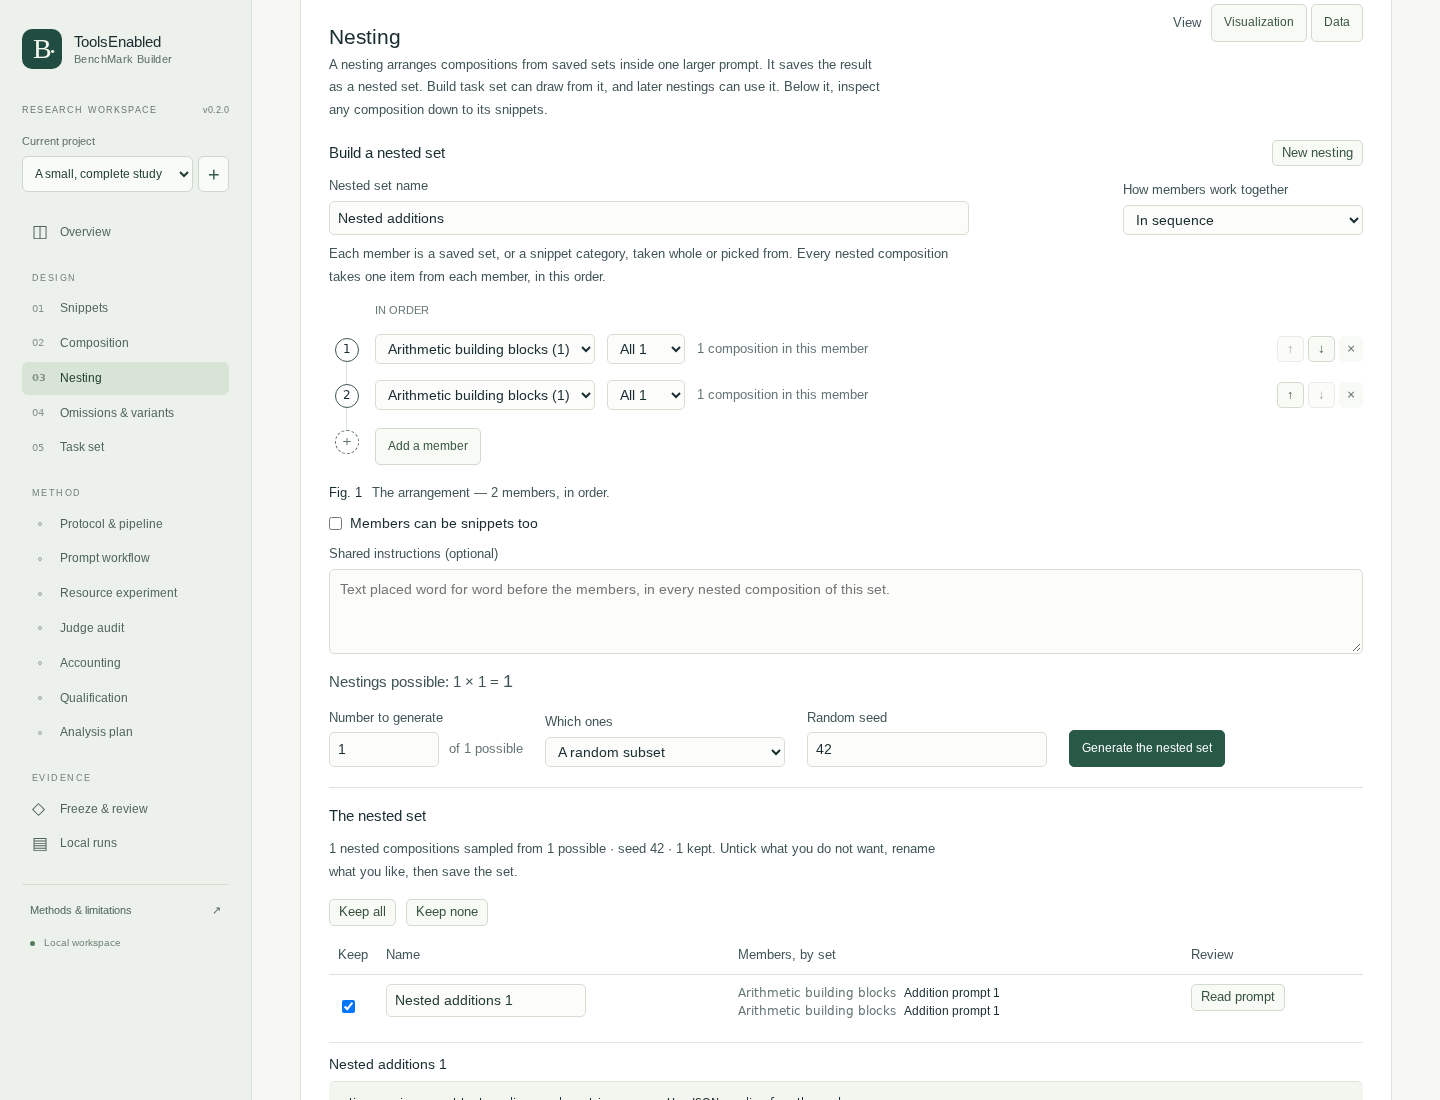
A saved composition is reused twice in a sequential nested set. This is an authoring preview, not an evaluated nested benchmark.
Nesting. A saved composition is reused twice in a sequential nested set. This is an authoring preview, not an evaluated nested benchmark.
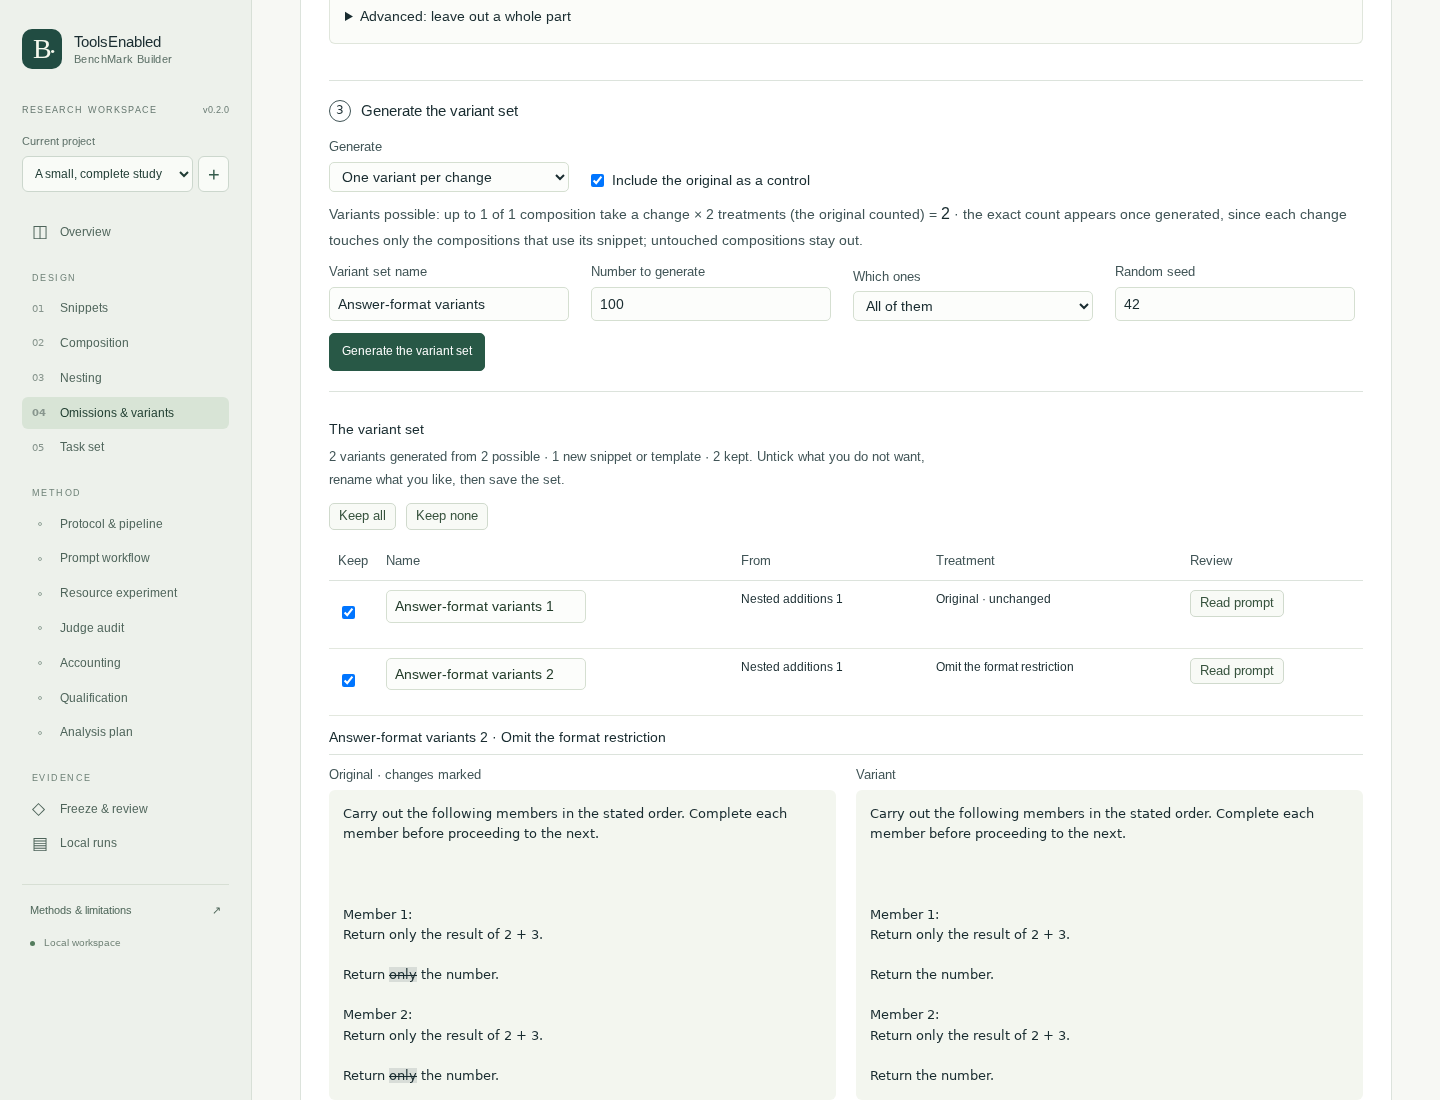
The original prompt and omission variant appear side by side, with the changed word marked and the original retained as a control.
Variants and omissions. The original prompt and omission variant appear side by side, with the changed word marked and the original retained as a control.
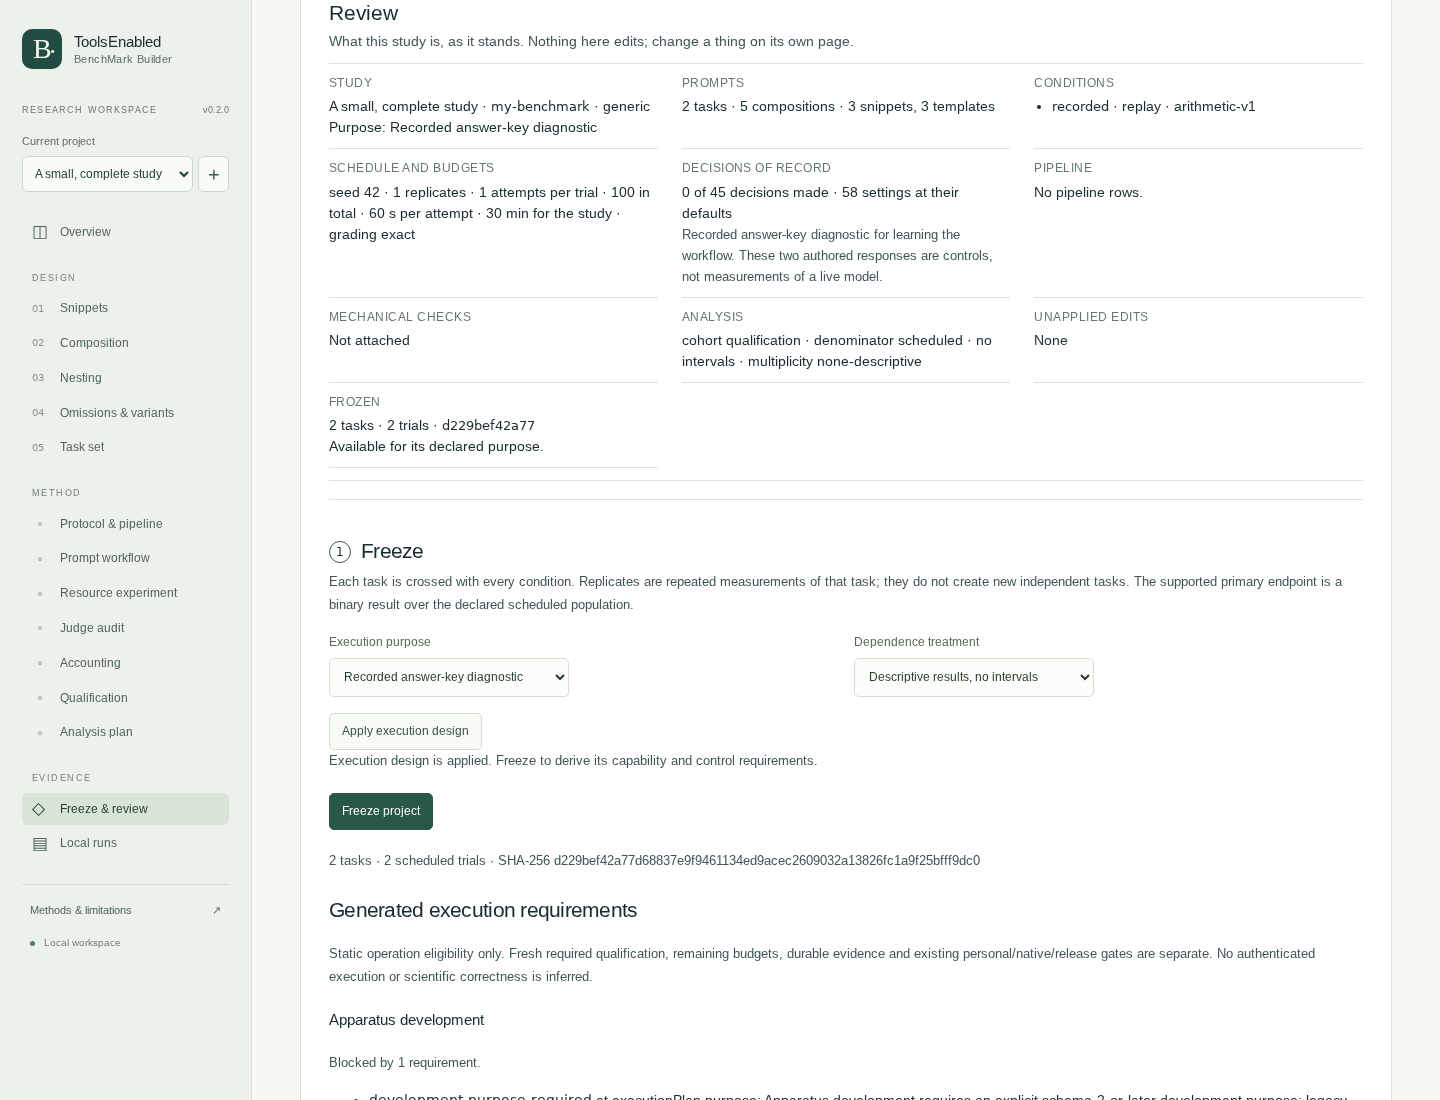
The review shows the protocol, schedule, purpose and frozen SHA-256 identity for two recorded-control tasks.
Freeze. The review shows the protocol, schedule, purpose and frozen SHA-256 identity for two recorded-control tasks.
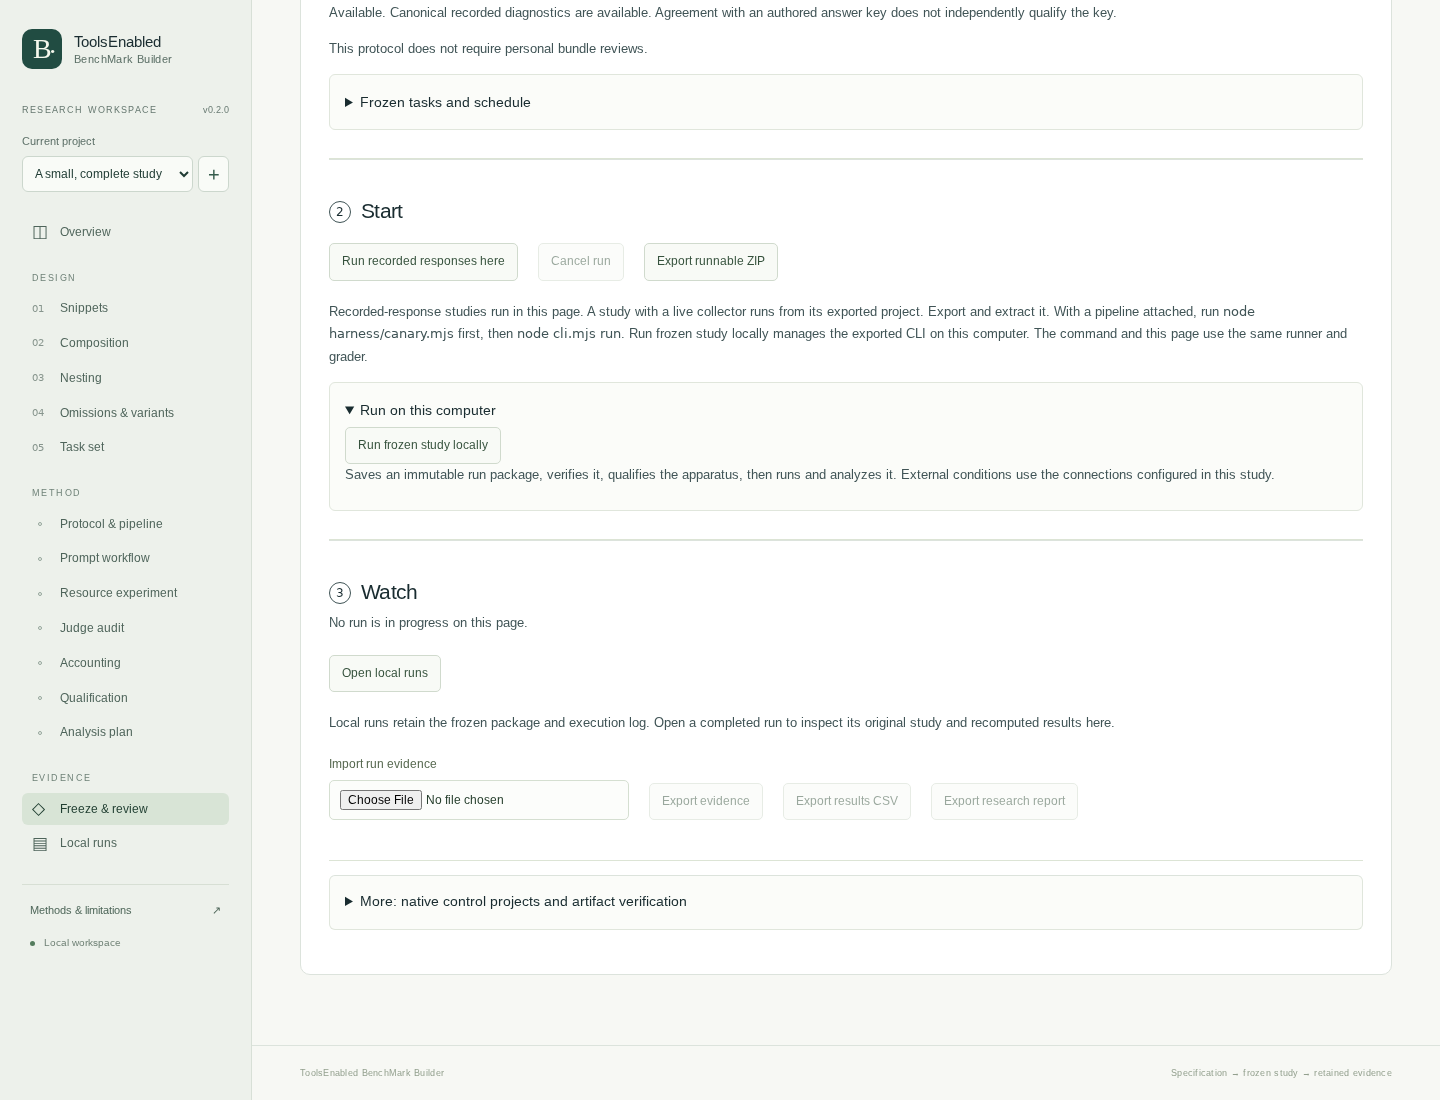
The frozen study offers its runnable ZIP and local CLI execution. The capture journey downloaded the actual package.
Portable export. The frozen study offers its runnable ZIP and local CLI execution. The capture journey downloaded the actual package.
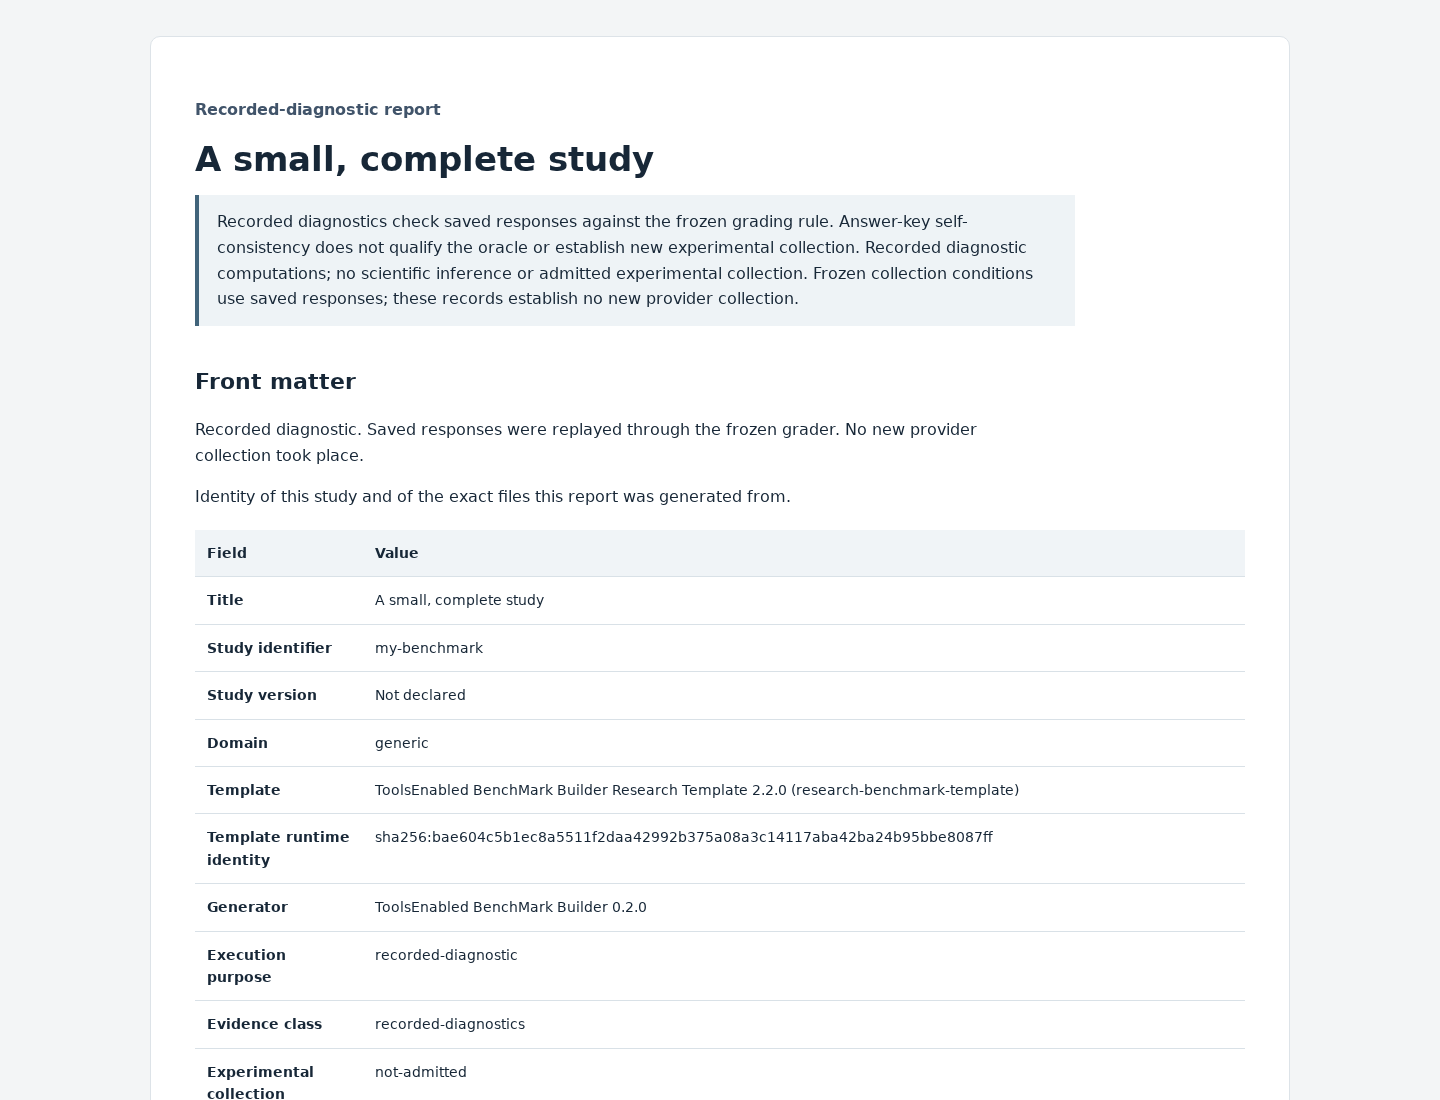
The actual HTML report downloaded from the completed local run identifies the study, template and recorded-diagnostic limits.
Retained report. The actual HTML report downloaded from the completed local run identifies the study, template and recorded-diagnostic limits.

03For your AI agent

Your agent runs
the study.

Bench 0.3.1 includes a local MCP server. Claude Code, Codex, Cursor, Claude Desktop, DeepSeek Harness or any other MCP host can compose, freeze, export, qualify, run, analyze and report a study through 12 tools, on the same local data as the web app.

PRINT THE SETUP FOR YOUR CLIENT
node tools/mcp-config.mjs --client claude
# or: codex | cursor | claude-desktop | deepseek

The helper only prints the registration; it changes nothing. Running or qualifying a study requires its exact study ID as explicit confirmation, and a study from someone else also requires explicit trust. One Bench process uses a data folder at a time, so the web app and the MCP server never write the same folder at once. Claude Code and Codex ask you before these calls by default.

Tested on the 0.3.1 release: real Claude Code, Codex and DeepSeek Harness sessions each ran the included example end to end through MCP, and their exported studies were byte-identical. Client names are trademarks of their owners; ToolsEnabled is not affiliated with or endorsed by them.

04Run locally

Take the study
with you.

The prebuilt release serves locally with Node.js 22.19 or later, without package installation or a network connection. The service binds only to 127.0.0.1 and checks the Host and Origin of every request; projects and evidence stay in its local data directory.

EXTRACTED RELEASE
node tools/release.mjs --verify
node server/main.mjs
# then open http://127.0.0.1:4318

An exported study carries its pinned runtime, required plugins and file hashes. Run it with its own CLI:

EXPORTED STUDY
node cli.mjs verify
node cli.mjs qualify
node cli.mjs run
node cli.mjs analyze

The 0.3.1 download keeps its recorded package name, ToolsEnabled BenchMark Builder: toolsenabled-benchmark-builder-0.3.1.zip. External data collection needs the environment a study declares.

05Scope

What the evidence
does and doesn’t say.

  • EXAMPLES

    The shipped examples and acceptance checks use authored, recorded controls. Bench publishes no live-model scores or comparisons.

  • FREEZE

    A frozen hash establishes content identity. It is not a prospective registration, a publisher signature or an independent validation.

  • REPORTS

    Analysis and reports regenerate from preserved artifacts with the pinned runtime. Newly collected stochastic responses need not match earlier ones.

  • TESTS

    Passing software tests and browser acceptance are bounded software checks, not a methodology audit, peer review or publication.

  • EXPORTS

    Exported studies are executable packages: inspecting a received study’s results doesn’t run its code, but running or re-grading it does. Run only studies you trust.

  • AGENTS

    The MCP server is local only; ChatGPT needs a hosted version, which is not part of this release. An agent that runs a study executes that study’s code with your permissions, just like the CLI.

  • SOURCE

    MIT licensed. Every public release gets a clean public source repository and tag: ToolsEnabled/toolsenabled-bench, tag v0.3.1.

Benchmarks you can
check.